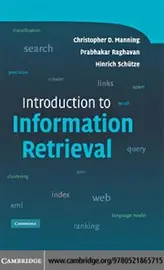
Introduction to information retrieval
Christopher D. Manning, Prabhakar Raghavan, Hinrich Schütze · 2008
Machine learning, statistics and probability › Deep learning and AI
#991 most recommended
Hacker News
45
mentions by 44 people · top 8% of 15,732 books
Open Library
5.00★★★★★★★★★★
1 rating · 11 want to read
Wikipedia
—
No article yet
About the book
The book covers how systems gather, index, search, and rank text documents, from classical Boolean and vector-space retrieval through web search with crawling and link analysis. It also treats the related tasks of text classification and text clustering, and the methods used to evaluate retrieval systems. Its central claim is that a small set of foundational techniques, such as inverted indexes, term weighting, and probabilistic or machine-learned ranking, underlies both classical document retrieval and web search. It holds that retrieval quality has to be measured with explicit evaluation methods like precision, recall, and relevance judgments rather than assumed. It also presents classification and clustering as machine learning methods that apply to the same text collections.
Written by Claude from what it knows of this book.
What Hacker News says 93% recommend · 2% critical
In the commenters’ own words
I've been thinking for a while of building a domain-specific / "vertical" search engine. I usually end up telling myself it's crazy to think that I can…
Well yes a ton :) And these are the ones off the top of my head... others feel free to list ones I'm missing Books: Lucene in Action…
What Open Library readers say 5.00 from 1 rating
- 51
- 40
- 30
- 20
- 10
- 11 want to read
- 1 reading
- 1 have read
Only 1 rating: treat the average as a hint.
What critics say, via Wikipedia
No Wikipedia article about this book yet, so no critics to quote.
Reddit communities — coming later
The threads it came up in
Details
- First published
- 2008
- ISBN
- 9780521865715
- Editions known
- 10 at Open Library
- Open Library
- OL14866497W
Computer TechnologyDocument clusteringInformation organizationInformation retrievalInformation storage and retrieval systemsNonfictionSemantic WebText processing (Computer science)
Read next: its neighbours on the mosaic
 Modern information retrievalR. Baeza-Yates · 1999 · recommended by 4 people · 2 people recommended both
 Lucene in actionMichael McCandless · 2010 · recommended by 5 people · 2 people recommended both
 Speech and language processingDan Jurafsky · 2000 · recommended by 41 people · 4 people recommended both
 Search user interfacesMarti Hearst · 2009 · recommended by 3 people · 2 people recommended both
 Mining of massive datasetsAnand Rajaraman · 2012 · recommended by 17 people · 2 people recommended both
 The Elements of Statistical LearningTrevor Hastie · 2001 · recommended by 144 people · 3 people recommended both
 Data miningI. H. Witten · 1999 · recommended by 9 people · similar by subject and what people say about it
 Managing gigabytesIan H. Witten · 1999 · recommended by 26 people · similar by subject and what people say about it
 Introduction to AlgorithmsThomas H. Cormen · 1990 · recommended by 274 people · 3 people recommended both
 Programming Collective IntelligenceToby Segaran · 2007 · recommended by 86 people · 2 people recommended both
 Information Theory, Inference & Learning AlgorithmsDavid J.C. MacKay · 2003 · recommended by 77 people · 2 people recommended both
 Natural Language Processing With PythonEdward Loper · 2009 · recommended by 25 people · similar by subject and what people say about it
 Introduction to Statistical LearningGareth James · 2021 · recommended by 85 people · similar by subject and what people say about it
 Learning From DataYaser S. Abu-Mostafa · 2012 · recommended by 31 people · similar by subject and what people say about it
 Neural Networks and Deep LearningCharu C. Aggarwal · 2018 · recommended by 72 people · similar by subject and what people say about it
 Pattern Recognition and Machine LearningChristopher M. Bishop · 2008 · recommended by 80 people · similar by subject and what people say about it
 Artificial IntelligenceStuart J. Russell · 1994 · recommended by 60 people · similar by subject and what people say about it
 Deep LearningIan Goodfellow · 2016 · recommended by 44 people · similar by subject and what people say about it
 Taming TextGrant Ingersoll · 2012 · recommended by 6 people · similar by subject and what people say about it
 Foundations of Statistical Natural Language ProcessingChristopher Manning · 1999 · recommended by 15 people · similar by subject and what people say about it
 Algorithms of the intelligent webHaralambos Marmanis · 2009 · recommended by 5 people · 2 people recommended both
 Bayesian reasoning and machine learningDavid Barber · 2011 · recommended by 15 people · similar by subject and what people say about it
 Readings in database systemsMichael Stonebraker · 1998 · recommended by 11 people · similar by subject and what people say about it
 Convex optimizationStephen P. Boyd · 2006 · recommended by 40 people · 2 people recommended both