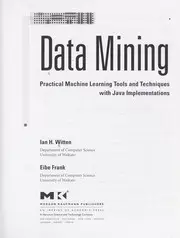
Data mining
I. H. Witten, Ian H. Witten, Eibe Frank · 1999
Machine learning, statistics and probability › Deep learning and AI
#2,812 most recommended
Hacker News
20
mentions by 14 people · top 17% of 15,732 books
Open Library
—
No ratings yet
9 want to read
Wikipedia
—
No article yet
About the book
The book covers machine learning as applied to data mining: preparing input data, choosing and running algorithms, interpreting their output, and evaluating results. It surveys classic and more recent methods, including decision trees, rule learning, linear models, instance-based learning, clustering, and Bayesian approaches, and it is tied to the Weka workbench, a Java toolkit. The central claim is that useful data mining depends as much on how data is represented and prepared, and on how results are evaluated, as on the choice of algorithm. Simple methods often perform well on practical problems, and their assumptions and limits should be understood rather than treated as black boxes. The authors also argue that honest evaluation, such as held-out test data and cross-validation, is necessary before any learned model's performance can be trusted.
Written by Claude from what it knows of this book.
What Hacker News says 64% recommend · 7% critical
In the commenters’ own words
I recommend starting with Witten and Frank's "Data Mining: Practical Machine Learning Tools and Techniques", for two reasons: 1) your mathematical background…
"the defining moment of the Web 2.0 revolution was Google's invention of PageRank" Huh? PageRank dates from the late 90s. And it's implemented in a compiled…
What Open Library readers say
No Open Library reader has rated it yet.
- 9 want to read
- 1 reading
- 1 have read
What critics say, via Wikipedia
No Wikipedia article about this book yet, so no critics to quote.
Reddit communities — coming later
The threads it came up in
Details
- First published
- 1999
- ISBN
- 9780120884070
- Editions known
- 12 at Open Library
- Open Library
- OL3961218W
077762Artificial Intelligence - GeneralArtificial intelligenceComputer Bks - Data Base ManagementComputer Books: Internet GeneralComputersComputers - Data Base ManagementComputers / Information Storage & RetrievalData Modeling & DesignData capture & analysisData miningDatabase EngineeringDatabase Management - Database Mining
Read next: its neighbours on the mosaic
 Data miningJiawei Han · 2000 · recommended by 4 people · similar by subject and what people say about it
 Machine learningStephen Marsland · 2009 · recommended by 5 people · similar by subject and what people say about it
 Collective intelligence in actionSatnam Alag · 2008 · recommended by 4 people · similar by subject and what people say about it
 Machine learningKevin P. Murphy · 2012 · recommended by 15 people · similar by subject and what people say about it
 Pattern Recognition and Machine LearningChristopher M. Bishop · 2008 · recommended by 80 people · similar by subject and what people say about it
 Introduction to information retrievalChristopher D. Manning · 2008 · recommended by 41 people · similar by subject and what people say about it
 Programming Collective IntelligenceToby Segaran · 2007 · recommended by 86 people · similar by subject and what people say about it
 The Elements of Statistical LearningTrevor Hastie · 2001 · recommended by 144 people · similar by subject and what people say about it
 Introduction to Statistical LearningGareth James · 2021 · recommended by 85 people · similar by subject and what people say about it
 All of StatisticsLarry Wasserman · 2004 · recommended by 40 people · similar by subject and what people say about it
 Learning From DataYaser S. Abu-Mostafa · 2012 · recommended by 31 people · similar by subject and what people say about it
 Data SmartJohn W. Foreman · 2013 · recommended by 20 people · similar by subject and what people say about it
 Deep LearningIan Goodfellow · 2016 · recommended by 44 people · similar by subject and what people say about it
 Mining of massive datasetsAnand Rajaraman · 2012 · recommended by 17 people · similar by subject and what people say about it
 Hands-On Machine Learning with Scikit-Learn and TensorFlowAurélien Géron · 2017 · recommended by 16 people · similar by subject and what people say about it
 Python Data Science HandbookJake VanderPlas · 2016 · recommended by 8 people · similar by subject and what people say about it
 Machine LearningTom M. Mitchell · 1997 · recommended by 16 people · similar by subject and what people say about it
 Foundations of Data ScienceAvrim Blum · 2020 · recommended by 7 people · similar by subject and what people say about it
 Python machine learningSebastian Raschka · 2015 · recommended by 5 people · similar by subject and what people say about it
 Hands-On Machine Learning with Scikit-Learn, Keras, and TensorFlowAurélien Géron · 2019 · recommended by 8 people · similar by subject and what people say about it
 Bayesian reasoning and machine learningDavid Barber · 2011 · recommended by 15 people · similar by subject and what people say about it
 Python For Data AnalysisWes McKinney · 2012 · recommended by 29 people · similar by subject and what people say about it
 Machine learning for hackersDrew Conway · 2012 · recommended by 6 people · similar by subject and what people say about it
 Algorithms of the intelligent webHaralambos Marmanis · 2009 · recommended by 5 people · similar by subject and what people say about it