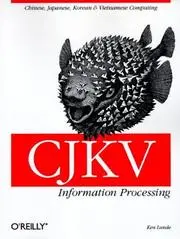
CJKV information processing
Ken Lunde · 1998
Programming and computer science › Programming classics and Java
#15,485 most recommended
Hacker News
2
mentions by 2 people · top 79% of 15,732 books
Open Library
—
No ratings yet
Wikipedia
—
No article yet
About the book
The book covers the computer processing of Chinese, Japanese, Korean and Vietnamese text, collectively called CJKV. Its scope includes the character sets and encodings used for these languages, along with their fonts, input methods, sorting, and the software that handles them, with Unicode discussed alongside the older national standards. Lunde's central point is that CJKV text cannot be handled with the assumptions that suit single-byte alphabetic scripts, because each language has its own character repertoire, encoding schemes and conventions. The book lays out the standards landscape so that developers can see how these pieces fit together. It presents Unicode as a route to interoperability while documenting the legacy encodings that remained in use, and it treats correct support as a matter of understanding the standards and their trade-offs rather than of ad hoc workarounds.
Written by Claude from what it knows of this book.
What Hacker News says 50% recommend · 0% critical
In the commenters’ own words
Hello HN, I'm looking for good books on how to process Arabic texts. I'm looking in particular for a description the various encoding and character sets, how…
Honestly the amount of crazy code involved in Linux font rendering[1], and then you get to CJKV support[2], it's mind-boggling. Even then, it's nowhere near…
What Open Library readers say
No Open Library reader has rated it yet.
What critics say, via Wikipedia
No Wikipedia article about this book yet, so no critics to quote.
Reddit communities — coming later
The threads it came up in
Details
- First published
- 1998
- ISBN
- 9780596156114
- Editions known
- 2 at Open Library
- Open Library
- OL3409762W
Chinese languageComputational linguisticsComputer programsData processingElectronic data processingJapanese languageKorean languageOriental languagesVietnamese language
Read next: its neighbours on the mosaic
 USB completeJan Axelson · 1999 · recommended by 6 people · loosely similar by subject
 Learning How to LearnBarbara Oakley · 2018 · recommended by 13 people · loosely similar by subject
 Visual languageRobert E. Horn · 1998 · recommended by 1 person · loosely similar by subject
 Spoken language processingXuedong Huang · 2001 · recommended by 2 people · loosely similar by subject
 Unix text processingDale Dougherty · 1987 · recommended by 6 people · loosely similar by subject
 Java CookbookIan F. Darwin · 2001 · recommended by 2 people · loosely similar by subject
 Mandarin ChineseCharles N. Li · 1989 · recommended by 0 people · loosely similar by subject
 JavaJim Waldo · 2010 · recommended by 0 people · loosely similar by subject
 J for C Programmersrecommended by 17 people · loosely similar by subject
 Understanding Geometric AlgebraKenichi Kanatani · 2015 · recommended by 1 person · loosely similar by subject
 The Cambridge encyclopedia of languageDavid Crystal · 2010 · recommended by 1 person · loosely similar by subject
 Japanese, The Spoken LanguageEleanor Harz Jorden · 1987 · recommended by 4 people · loosely similar by subject
 AI algorithms, data structures, and idioms in Prolog, Lisp, and JavaGeorge F. Luger · 2009 · recommended by 1 person · loosely similar by subject
 Visualizing DataBen Fry · 2008 · recommended by 7 people · loosely similar by subject
 MVS JCLDoug Lowe · 1987 · recommended by 0 people · loosely similar by subject
 Database System ConceptsKorth · 2005 · recommended by 4 people · loosely similar by subject
 Virtual MachinesJim Smith · 2005 · recommended by 3 people · loosely similar by subject
 Chinese Cursive ScriptFang-yu Wang · 1958 · recommended by 2 people · loosely similar by subject
 Coded Character SetsCharles E. MacKenzie · 1979 · recommended by 1 person · loosely similar by subject
 VIC BASICRamon Zamora · 1983 · recommended by 0 people · loosely similar by subject
 Understanding SoftwareMax Kanat-Alexander · 2017 · recommended by 2 people · loosely similar by subject
 Transaction processingGray, Jim · 1993 · recommended by 13 people · loosely similar by subject
 Using C on the UNIX systemDavid A. Curry · 1989 · recommended by 1 person · loosely similar by subject
 Zen of Exotic ComputingPeter M. Kogge · 2022 · recommended by 1 person · loosely similar by subject